1.LLM Provider Cost and Latency Evaluation
ML lead · 2026
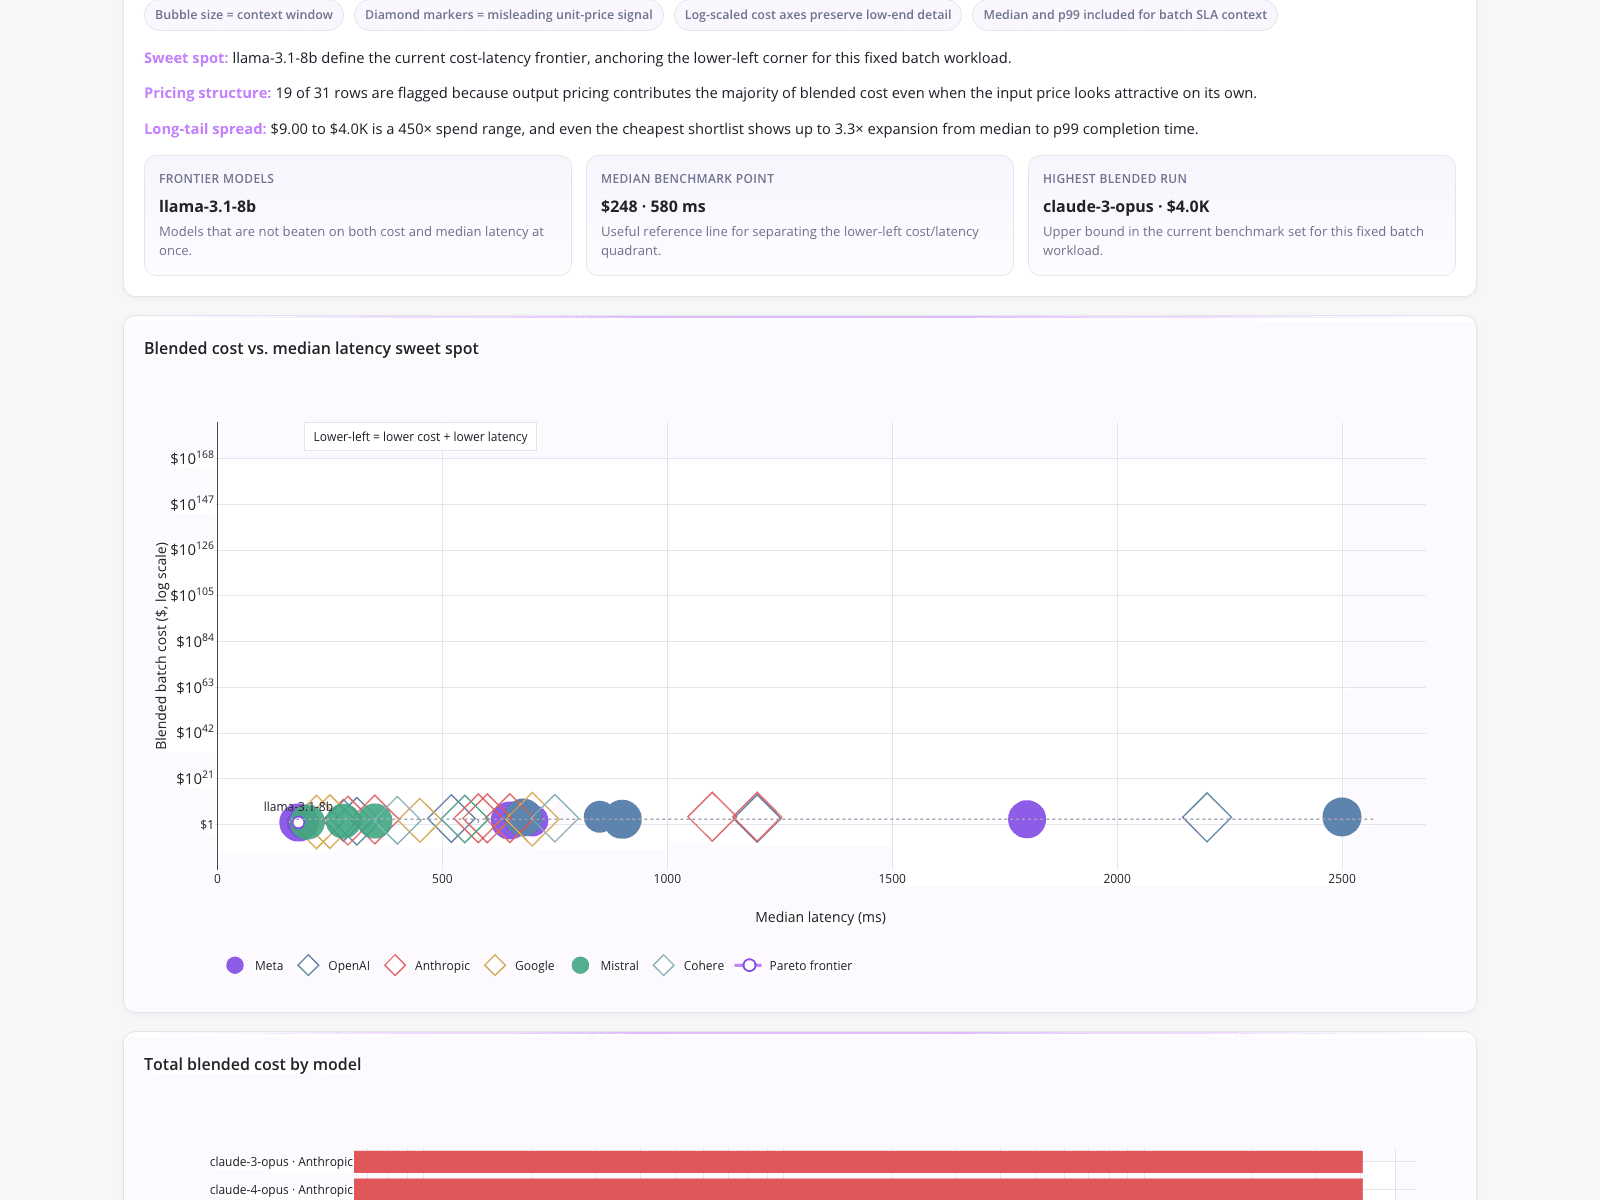
An ML lead evaluated 31 models across 6 providers for a 300,000-record bulk text-structuring workload to determine the most cost-effective rag implementation. The dashboard features KPI cards and a log-scaled scatter plot mapping blended batch cost against median latency, revealing a 450x spend range from $9.00 to $4,000. By identifying llama-3.1-8b as the frontier model with a 180 ms latency and flagging 19 models for misleading pricing, the engineering team secured procurement sign-off based on a defensible cost-latency tradeoff.
What it shows:
Visualizing blended batch costs against median latency enables engineering teams to secure procurement sign-off for frontier models.
#llm-cost-analysis#provider-benchmarking#latency-metrics