1.Multilingual Text Extraction Defect Tracking
Data Research · 2026
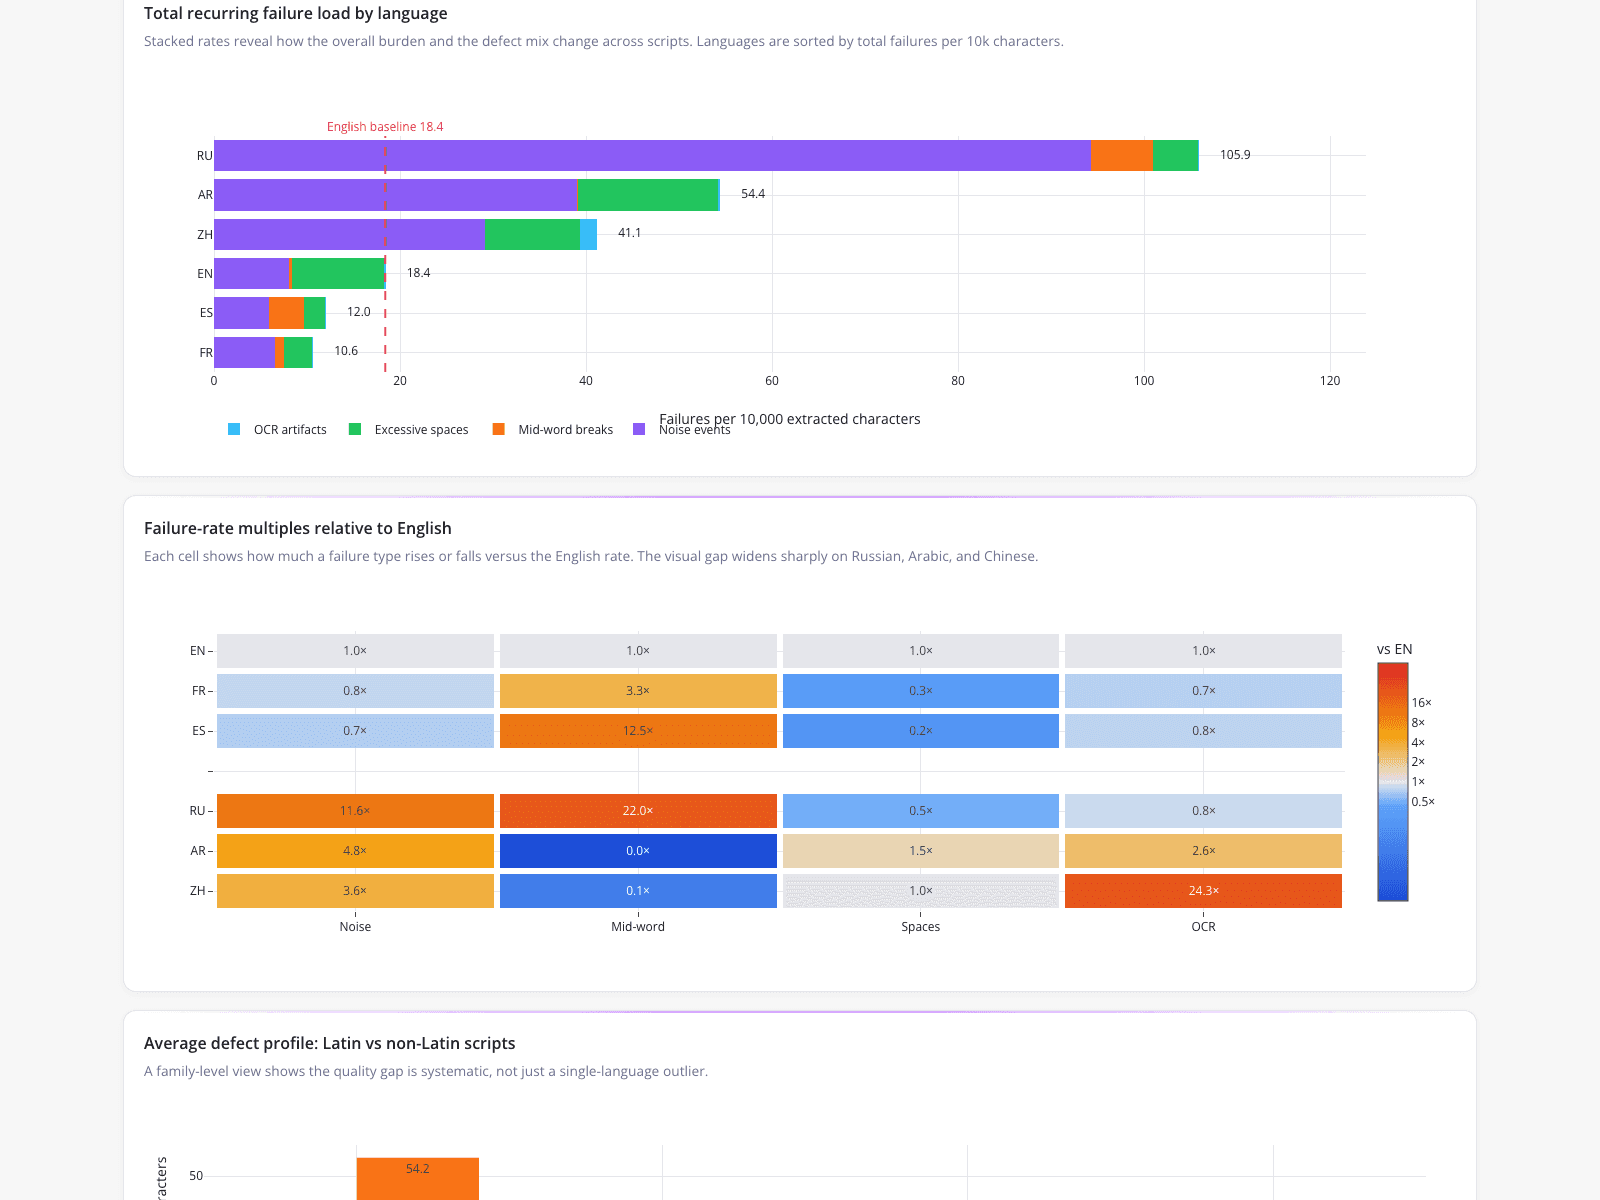
A multilingual data researcher utilized a dashboard to quantify severe text extraction degradation across six languages, directly supporting the need for accurate OCR PDF to Excel workflows. The visualizations display a stacked bar chart where Russian exhibits the highest defect rate at 105.9 failures per 10,000 characters, significantly exceeding the English baseline of 18.4, while a heatmap reveals Chinese OCR artifacts occur at 24.3 times the English rate. By aggregating the average defect profile for non-Latin scripts at 54.2, the researcher definitively proved pipeline failures and provided concrete metrics to justify targeted remediation.
What it shows:
Quantifying character-level defects justifies targeted remediation for non-Latin scripts.